Your models, your infrastructure,
your data
Run open language models in your own server room or private cloud: confidentiality, predictable costs, controlled latency and independence from API providers.
Why host the model instead of consuming an API
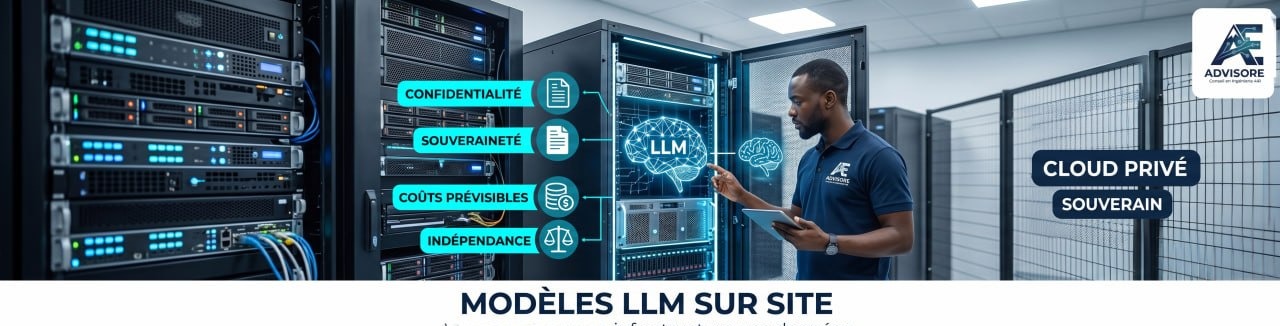
Confidentiality
The requests and documents being processed never leave your infrastructure. That point alone often decides the matter.
Sovereignty
You know where the data is, who can reach it and under which jurisdiction it is processed — and you can demonstrate it.
Predictable costs
An amortised infrastructure investment rather than a variable expense that follows usage. Consumption no longer depends on someone else's price list.
Latency and continuity
Immediate answers on the local network, and a service that is not interrupted by an international outage or by a change of terms at a provider.
Independence
Changing model becomes an internal technical decision again: you are no longer bound to a third party's commercial or retention policy.
Lifecycle control
You decide when to update, when to freeze a version and how long usage logs are kept.
How we deploy a model on site
Size the platform
Volumes, nature of the tasks, number of users, power, cooling and floor-space constraints.
Choose the open models
Model families, sizes, licences, languages covered and quality measured on your own documents.
Prepare the hardware
Dedicated servers and accelerators, memory, storage, power redundancy, hardware monitoring.
Containerise
Reproducible deployment, controlled updates, separate test and production environments.
Quantise and optimise
Lower weight and cache precision so that the model fits the available memory and answers faster.
Open an internal gateway
A single entry point for applications: authentication, quotas, filtering, model selection according to how sensitive the request is.
Log and test
A log of requests and responses, quality measurement, regression tests on every model change.
On site or through an API: what actually changes
| Criterion | On site | Public API |
|---|---|---|
| Confidentiality | Data does not leave the company | Data is sent to a third party under a contract |
| Cost | Hardware investment, then operations and power costs | Variable expense that follows usage, with no initial investment |
| Latency | Answers on the local network, independent of international bandwidth | Depends on the quality of the international connection |
| Skills required | Operations, monitoring and updates must be covered internally | Local effort limited to application integration |
| Evolution | Model changes are your decision | Depends on the provider's versions and terms |
| Connectivity outage | The service keeps running | The service becomes unavailable |
Both approaches can coexist: sensitive processing on site, non-sensitive tasks through an API.
When a public API remains the better choice
- When volumes are low and irregular: a dedicated server is not justified yet.
- When the data processed is not sensitive and may leave the company under a contractual framework.
- When you need the best available model immediately, with no lead time.
- When you have neither a server room nor operations staff to dedicate to the subject.
- As an interim solution while an in-house deployment is being prepared.
Decide on facts, not on fashion
We examine your data, your infrastructure and your operational constraints, then write a reasoned recommendation — including when it is to deploy nothing on site at all.